Chapter 12.4: Other Methods of Word Formation

chapter 12.4: other methods of word formation

In addition to adding derivational morphemes to a root morpheme, there are other
ways of joining morphemes together to create new words. Here is a brief discussion
of the most common.

Compounding

Words can be created by taking two or more free morphemes and joining them together
into compounds. There are different ways of classifying compounds.
The simplest way is to categorize them by the different parts of speech that are
joined together. Thus we have the following types:

  1. Noun-Noun: bedroom, eyeball, peanut butter, airplane, fireplace, waterbed.
    In each of these, the first element modifies the second element, which is
    called the head. The head is the part which contains the basic
    semantic meaning of the compound (note that in some languages, the head comes
    before the modifier). Also note that our orthographic conventions regarding
    spacing do not have an effect on whether or not a word is a compound. Thus,
    peanut butter is a single compound, where butter is the head
    and is modified by peanut; peanut butter sandwich is also a
    compound, where sandwich is the head and peanut butter is
    the compound noun modifier. It makes no difference that we use spaces in
    writing these compounds but we don’t in bedroom.
  2. Adjective-noun: blackbird, redhead, blueblood. These can be
    differentiated from standard adjective + noun phrases primarily through
    stress (prosody). Thus, the phrase black bird (as in “That is a
    black bird”) is accentuated on both syllables: bláck bírd. The
    compound, describing a species of bird, such as
    Turdus merula,
    is accentuated only on the first syllable: bláckbird. As with noun-noun
    compounds, the head is the right-hand element while the first element is the
    modifier.
  3. Verb-noun: killjoy, cutthroat, breakfast. These are usually analyzed
    as a person or thing that X’s Y, where X is the verb and Y is the noun.
    Thus a killjoy is someone that kills joy. A breakfast
    is a meal that breaks one’s fast, and so on. These are relatively
    rare in English.

For less common categories of compounds, such as verb+verb (freeze-dry), adjective+adjective (blue-green),
or verb-adjective (spendthrift) you can review the wikipedia page
on English compounds.

Another way of classifying compounds is into endocentric and
exocentric groups. Most of the examples above are endocentric
compounds, that is, they contain the head within the compound itself. Thus, a
bedroom contains the word room in it, and describes a room
that has a bed in it. On the other hand, the term redneck does not describe a
neck that is red. This is an exocentric compound,
because the “head” of the compound is a person, who (figuratively) happens to
have a red neck. Compounds like this are more commonly called bahuvrihi
compounds, after a Sanskrit word that means “much rice,” meaning a rich person (i.e.,
someone who possesses much rice). Other examples in English are blueblood,
redhead, blockhead, white-collar
.

Finally, there are obscured compounds, compounds whose elements
were at one time free morphemes, but which are no longer identifiable as such due to changes
in the language. Thus, we have the following words in Modern English, which were
originally compounds in Old English: orchard (plant-yard), lady
(bread-kneader), lord (bread-guardian), nostril (nose-hole),
window (wind-eye), hussy (house-wife), warlock(oath-breaker),
gospel (good-story), garlic (spear-leak), and so on. Today,
each of these words would be considered simplexes rather than compounds.

Portmanteau words and blends

A portmanteau is a word that blends two morphemes
into a single morpheme. Common examples are brunch (breakfast+lunch),
ginormous (giant+enormous), and motel
(motor+hotel). Newer examples are manscaping, mansplaining,
spork, jeggings, brony, Brangelina, sexting,
etc. Sometimes these are also called blends, and some linguists distinguish between
blends and portmanteaux.

Some people consider the following morphemes under the category of portmanteaux
rather than suffixing: –thon, -gate, -lympics, -mageddon. This may be
partially correct, but they may be on their way to becoming suffixes. With portmanteau
words there is a blending of phonemes from each word into a single morpheme.
Consider the word marathon, originally a place name, but introduced into
English in 1896 to describe a long race. We can add the end of this word to the
beginning of a word such as television to get telethon, describing
an especially long television program. But many words to which –thon can
be added are not truncated: consider
walkathon or Toyotathon. In these examples, -(a)thon acts
more like a suffix than a blend. In fact, the word walkathon was first
used in 1931, 18 years before telethon was first used. Similarly,
gate does not indicate any connection with the Watergate hotel, but simply
means “political scandal,” and is usually added to complete rather than shortened morphemes.

The morpheme –lympics also seems to act midway between a portmaneau and
a suffix, since the primary use is in the word paralympics, a clear blend
of paraplegic and olympics. We also have the
Laff-A-Lympics and something
called the E-lympics,
both of which are based on Olympic-style contests. Its use in these
newly-created words suggests a productive quality that is not usually found in other
portmanteau words (i.e., we have the word brunch, but we don’t find *brinner
or *brupper, let alone *bridnight-snack).

Reduplication

English does not currently use reduplication, but it used to. Reduplication was
a primary method of creating the past tense of verbs, as you might know if you
happen to have studied Greek, Sanskrit, Latin or an early Germanic language like Gothic. In
Gothic the verb slepan “to sleep” formed its past tense sai-slep,
by reduplicating the initial s- into a new syllable at the front of a word. There
are a few words in Old English that preserve traces of reduplication, but it had
largely disappeared even by then. There is only one word
in (sort of) modern English which preserves a trace of reduplication:
the very old-fashioned word hight, meaning “to be named,” which occurs in
Chaucer, Spenser, and some particularly archaic-sounding 19th-century poetry.
The “gh” in the middle of the word was originally the beginning of the word and
the initial hi– was the reduplicating syllable.

Morpheme Internal Change (also called apophony)

Although most English nouns and verbs add inflectional suffixes to the end of the
root morpheme to signify different grammatical functions, there are many that make
internal changes to the morpheme instead. There are two types of morpheme internal
change in English.

  1. 1. Umlaut or mutation: Words affected by a front
    mutation of the vowel. For example, while most nouns make their plurals by adding the
    inflectional morpheme –s, others change the vowel within the base morpheme:
    foot/feet, tooth/teeth, goose/geese; mouse/mice, louse/lice; and man/men, woman/women.
  2. 2. Ablaut or Gradation: While most verbs make
    the past tense by adding an –ed morpheme, there are a large number that make vowel
    changes to form tenses: drive/drove/driven, bite/bit/bitten, ring/rang/rung,
    steal/stole/stolen, etc.

Suppletion

Suppletion is not so much the creation of a new morpheme as the substituting of
one morpheme for another. Suppletion is found throughout the language. For example,
while most adjectives make comparative and superlative
forms by adding the inflectional morphemes –er and –est, such as
tall, tall-er, tall-est, others simply use an entirely
different, originally unrelated morpheme. The comparative and superlative forms of
good are not *gooder and *goodest but better
and best, both formed from an archaic adjective bet that we no
longer use. Some verbs do this too. The past tense of go is went,
originally the past tense of the somewhat obsolete verb wend.
The verb to be uses three originally different verbs in its formation:
the beforms, the am/is forms and the was/were forms.
One tends to find suppletion in only the most common of words.


Chapter 12.3: Word Formation by Derivation

chapter 12.3: word formation by derivation

The joining of morphemes together into “words” follows certain rules and patterns (i.e., it is another demonstration of how English works as a system). As native English speakers we all have an intrinsic understanding
of these rules as part of our linguistic competence. On this page we will discuss how words can be formed by the adding of derivational morphemes, that is, prefixes and suffixes.

The Hierarchical Structure of Morphemes

The derivational morphemes discussed in 5.1 have specific rules governing how they may be added to words. Consider again the example unlucky. The root morpheme, or base morpheme, in this word is luck, a noun. In other words, it is the
root or base to which affixes may be added. If we try to add the prefix un– to it we will realize that it does not “sound right” (using our notions of “acceptability”). Thus, *unluck does not make an acceptable word. The reason for
this is that the prefix un– is usually only added to adjectives as a way to negate their meaning. Consider the following examples: unhappy, unable, unused, uncouth, untold. Compare this with the results of
adding un– to nouns: *unsofa, *uncar, *uncomputer. None of these form acceptable English words.

(Note: there is a second un– prefix that has a separate origin, meaning “to reverse an action,” that is found before verbs, (unbind, unlock, uncover, undo); this prefix is often confused with the adjectival one
and has been so for centuries).

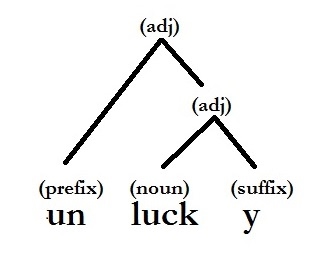
To return to unlucky, we see that in the order of progression for adding bound morphemes, we start with the base morpheme luck, and we first must make this into an adjective, by adding –y. This is a very common “adjectival
suffix
,” that is, it creates adjectives when it is added to a word (usually nouns, but sometimes also verbs or other adjectives). Lucky therefore means “characterized by luck” or “full of luck.” Once we have the adjective lucky,
we can negate it by adding the prefix un-. This process shows that there is a hierarchy or order in which bound morphemes may be added:

Hierarchy of Morphemes in Unlucky

Productive and Unproductive Affixes

The derivational morphemes like un- and -y are Germanic in origin, and so have been part of English since the English was first spoken. We can still use them today to create new words that have not been spoken before. Thus, they are called productive affixes. This means that they are still part of the lexicon that we understand and we consider the use of new words formed from them as acceptable (providing they follow the proper hierarchy). There are a large number of productive affixes: –ness, -ation, -ify, -ful, -age, -ish, and so on.

We have unproductive affixes as well. These are affixes that were once used in English but which we no longer use to form new words, simply because we no longer recognize them as having a semantic meaning. Consider the words strength, health, width, wealth, stealth, length, and breadth. They all end in the suffix –th. This is a suffix that was once used to make nouns out of adjectives (that is, it was a nominal suffix). Compare those nouns with the following adjectives (and one verb) from which they were formed: strong, hale, wide, weal, steal, long, broad. In spite of the existence of these nouns ending in –th, we cannot create new nouns from adjectives by adding this suffix. For example, we cannot make a new noun *wrongth (or more properly, *wrength) to mean “the state of being wrong” in the way that strength means “the state of being strong.”

Here is a list of English unproductive suffixes. You might want to look over this list so that you can see what the rules of adding these suffixes were, and try
to create new words with them. Maybe you can make them productive again.

A side note on the notion of “rules” and of “unproductive” as I am using these terms. When I say that un– can only be added to adjectives, I do not mean this as a prescriptive rule but as a descriptive rule. The only reason that we cannot add un– to nouns is that it does not sound “acceptable” to speakers of English. In fact, this unacceptability can even be exploited by companies looking to call attention to their products. Pepsi tried to distinguish 7-Up from other types of cola by calling it the Uncola, a word that, by not sounding quite right, calls attention to itself and thus the uniqueness of the product. Mercedes Benz tried to do the same for the Smart car, calling it an uncar. Interestingly, they also use the phrase unbig, another word which does not sound acceptable, which shows that there are other rules to the use of un– than simply adding it to adjectives. For example, it never occurs with adjectives describing
colors or sizes (*unblue, *unsmall) or with adjectives that express approval or disapproval (ungood, *unbad). Note George Orwell’s jarring use of ungood to mean “bad” and unlight to mean “dark” in 1984, which imagines a new form of language called Newspeak in which other such oddly formed words are used.

In spite of the usage of such terms in ads or literature, they still are not “acceptable” as part of everyday English. If one of them were to catch on, however, then the rules of acceptability would change.

The same principle of acceptability governs the notion of which affixes are productive and which aren’t. Affixes are unproductive simply because they are no longer used. If we started using them again, they would be considered productive. There is nothing inherent in the affix that makes it unsuitable for productivity.


Recently created affixes

Not all affixes are old. There are a number of fairly new affixes that are in quite common use. Perhaps the most common now is e– (for “electronic”), found on e-mail, e-trade, e-commerce, e-book, and so on. Other new ones are i-, –thon, –gate, –lympics, –mageddon. (On these last four, see under portmanteau).

Infixes

We have talked about prefixes and suffixes but have said nothing about infixes, which are rare in English. There are several unproductive infixes that were used in Proto-Indo-European or Proto-Germanic that still survive in English but are completely unrecognized as such now. For example, the n in the word stand is an infix, as you can tell by its absence in the past tense form stood. Its meaning apparently was as part of a present-tense marker (if you know Latin, you can find other examples of this same infix, such as present tense fundo “I pour” and past tense fudi, “I poured,” without the -n-).

There are only a few productive infixes in Present-Day English. The most common one uses the word “fucking” as the infix, which you may prefer not to use or to substitute with some phonetically similar combination such as “fricking.” Consider the words “abso-fucking-lutely,” “un-fucking-believable” and “fan-fucking-tastic.” This infix is an intensifying morpheme, and is often called “expletive infixation.” There are tamer versions of these such as “absoposilutely” with -posi- (from positive) substituted, and “fan-damn-tastic” but these are much less common.

Another infix comes in the form of –iz(n)-, originally in hip-hop and rap lyrics: h-iz-ouse, sh-izn-it, etc. These infixes might be considered prosodic morphemes since they change the rhythm of the words (useful in song lyrics), but they also add specific cultural coloring to the words. The use of this infix was popular for about a decade, but seems to have died out recently.

Finally, there is the so-called “Homeric infixation,” not named after the great Greek poet Homer, but after Homer Simpson. The Homeric infix is the -ma- in words like “edu-ma-cated” and “sophisti-ma-cation.” This infix gives words a pseudo-intellectual coloring.

(Note: Some linguists would say that none of the above are true infixes. The expletive infixes fail the test since they are free morphemes, not bound, derivational morphemes like the other affixes discussed here. The hip-hop and Homeric infixes fail since they do not change the meaning of the word in the way that derivational morphemes should. While these are fair objections, I do not feel like they are enough to disqualify them from being considered at least a type of infix).


Chapter 12.2: Types of Morphemes

Chapter 12.2: Types of Morphemes

There are two primary types of morphemes: free morphemes and bound morphemes.

Free Morphemes

A free morpheme can carry semantic meaning on its own and does
not require a prefix or suffix to give it meaning. In other words, it can stand
on its own as a word, like the, boy, run, and
luck. Each of these morphemes can function independently.

Bound Morphemes

Bound morphemes cannot stand alone but must be bound to other
morphemes, like –s, un-, and –y.

Bound morphemes are often affixes. This is a general term that
comprises prefixes, which are added to the beginnings of words,
like re– and un-, and
suffixes, which are added to the ends of words, like –s,
ly, and –ness. Some languages also have infixes,
which are added into the middle of words, but these are rare in Modern English.

Bound morphemes are further divided into two subtypes: derivational and
inflectional morphemes.

Derivational morphemes change the meaning or the part of speech
of a word (i.e., they are morphemes by which we “derive” a new word). Examples are
un-, which gives a negative meaning to the word it is added to,
y, which turns nouns into adjectives, or –ness, which
turns adjectives into nouns.

Inflectional morphemes add grammatical information to the word,
such as –s on runs, which tells us that it is 3rd person
singular present tense verb, or the –s on
boys, which tells us that there is more than one boy.

There are eight inflectional suffixes, often just called “inflections,”” in
English:

  • -s on verbs: 3rd person sg, present tense (he runs, she walks)
  • -ed on verbs: past tense: (I walked, they joined)
  • -ing on verbs: progressive (I was walking; they were joining)
  • -en on verbs: past participle (I was beaten; she has eaten)
  • -s on nouns: plural (boys, books)
  • -‘s on nouns; possessive (boy’s, book’s)
  • -er on adjectives: comparative (quicker, slower)
  • -est on adjectives: superla

Several of these inflections are similar phonologically, but do not confuse them.
The –s on the end of 3rd person singular verbs, the –s plural on
nouns, and the -‘s possessive ending are the same purely by
coincidence. Also, do not confuse the –ing inflectional ending used to
make verbs progressive (“I am singing”) with the derivational morpheme –ing
used to make verbs into nouns (“Singing is a fun thing to do”). They sound the same,
but they are used differently. Finally, do not let spelling confuse you. We signify
possessive plurals in spelling by adding an apostrophe to the end of the word
(e.g., boys’) but the only inflectional ending here is the s-plural. The apostrophe
is just a spelling convention.

Content vs Function Morphemes

There is one final distinction between different kinds of morphemes:

  • content morphemes, which have a clear semantic meaning (like book,
    luck, un-, –y, boy)
  • function morphemes, which include all inflectional morphemes like –s, and
    ed, but also include free morphemes such as the, of,
    with, and, but, and other similar words. These words
    signify the grammatical relationships between words and give structure to a
    sentence.

The wikipedia page on function words
has an excellent example of the difference
between content words and function words. Read these two sentences:

  1. The winfy prunkilmonger from the glidgement mominkled and brangified all
    his levensers vederously.
  2. Glop angry investigator larm blonk government harassed gerfritz infuriated
    sutbor pumrog listeners thoroughly.

In the first sentence, all the content words have been replaced with nonsense
words, but notice how the grammatical structure of the sentence is still clear.
You can tell that winfy is an adjective, that the words mominkled
and brangified are past tense verbs, and so on. In the second sentence
the content words are English but the function words have been replaced.
Without clear function words, this
sentence has no clear grammatical structure and is entirely incomprehensible!

Allomorphs

Allomorphs are non-meaningful variants of a morpheme. For example, the -s plural
takes three distinct phonological forms, [s], [z], and [ɪz], in the words
boys [bɔɪz], books [bʊks], and dishes [dɪʃɪz]. These
phonological distinctions are considered non-meaningful, making these allomorphs
of the -s plural morpheme.


Chapter 12.1: Morphemes

Chapter 12.1: Morphemes

A morpheme is the smallest unit of grammatical or semantic meaning
in a language. A morpheme is distinct from a phoneme because although a phoneme is the
smallest meaningful unit of sound in a language, by itself a /p/ or /m/ does
not have grammatical or semantic meaning. It must be combined with other phonemes
into a morpheme to have such meaning.

Consider the following words:

  • the
  • boy
  • runs
  • unlucky

The first two of these examples—the and boy
—are morphemes because it is impossible to divide them into smaller units
of grammatical or semantic meaning. For example, we cannot divide boy
into smaller units such as b- or -oy. The same is true of the.

The word runs, however, can be divided into two smaller units: run
and –s. Each of these has a distinct meaning. Run
has the semantic meaning “to move quickly on foot” and –s has the
grammatical meaning “3rd person singular present tense verb.”
Therefore, runs is made up of two morphemes, run and
s. The word unlucky can be divided into three morphemes:
un-, luck, and –y.

Note: Although all words in the English language are constructed from morphemes,
words and morphemes are not the same. A word can be made up of a single or multiple
morphemes. A syllables is also not the same as a morpheme. Syllables are units
of sound used for pronunciation. Some words may divide syllable by syllable into
morphemes, like unlucky, but others, like runs, contain two
morphemes in a single syllable.